
Lecture 11: The Economics of Ongoing Relationships
Something should have struck you as “off” in the discussion thus far.
We’ve been looking at a lot of betrayals. The prisoners’ dilemma, the centipede game, split or steal – in these situations, when there’s either a one-shot game or a game that ends, with the players never to see one another again, there is a strong incentive to “win” by acting in a selfish rather than a cooperative fashion.
But the world we see around us doesn’t – or at least, doesn’t always – work that way. We see people cooperate all the time, even when it’s not in their short-term interest to do so. We see generosity, and reciprocation. We see people give gifts, or take their friends out for coffee. Either the economic theories we’ve been looking at are nonsense, or there’s been something we’ve been leaving out.
Today I’m going to argue that the approach we’ve been taking hasn’t been wrong – we haven’t been making incorrect assumptions about human nature, or strategic behavior – but rather that the assumptions of our models have been incomplete. Specifically, we’re going to look at what happens when games are not played just once, but over and over. In other words, we’re going to look at the economics of ongoing relationships.
If you think about it, most relationships are not either finite or one-shot. Sure, two contestants may show up on a game show and never see one another again; but that’s a pretty contrived scenario. Most strategic relationships, be they competitive (like two oil companies) or cooperative (like a manager and an employee) are ongoing.
What we will see today is that in an ongoing relationship, players can sustain outcomes that would not be possible in a finite or one-shot game. The way we’ll model such a relationship is by saying that two players will play a game not once, but over and over again. While we can do this with dynamic games, it will be simplest to analyze the case in which two players play a simultaneous game multiple times. We will call the game which is repeated the “stage game.”
We’ll look at two specific models today:
- A finitely-repeated game with multiple Nash equilibria
- An infinitely-repeated game (or, as I prefer, an indefinitely-repeated game) with a single Nash equilibrium
What we’re going to find is that when a stage game is repeated, we’re able to sustain behavior that wouldn’t be a Nash equilibrium of the stage game, by making a credible promise about how to play in the future. Let’s start by looking at the shortest possible repeated game: a game that’s repeated twice.
Finitely Repeated Games
Consider the following stage game:
There are two Nash equilibria of this game: $(\pone{T}, \ptwo{L})$ and $(\pone{M}, \ptwo{C})$; these give payoffs of $(\pone{5}, \ptwo{2})$ and $(\pone{2}, \ptwo{4})$, respectively. But look at the bottom-right cell: that gives payoffs of $(\pone{7}, \ptwo{9})$! It would be awfully nice if they could play that; but if player 2 were playing $\ptwo{R}$, player 1’s best response would be to play $\pone{T}$, and get $\pone{9}$ rather than $\pone{7}$. So it’s not a Nash equilibrium; and if this game were only played once, it wouldn’t be possible to achieve.
But suppose the game is repeated twice, and that each player’s payoff is the sum of the payoffs in the two periods. In that case, each player’s strategy would have to specify what to do in the first game, and then what to do after every possible outcome of the first game. In other words, each player’s strategy has ten elements! In such a case, it’s easiest to write out strategies in words. For example, a strategy for player 1 might be “Play $\pone{T}$ in the first game. In the second game, play whatever the best response to whatever player 2 chose in the first game.”
With this repeated game, it’s actually possible to have a subgame-perfect Nash equilibrium in which each player’s strategies involve playing $(\pone{B}, \ptwo{R})$ in the first period, even though that’s not a Nash equilibrium of the stage game! Let’s see how.
First, let’s develop an important lemma:
Lemma : Suppose $s^\star$ is a subgame perfect Nash equilibrium of a finitely repeated game. In that case, in every subgame in the last period (that is, after every possible history of play), the strategies specified by $s^\star$ must constitute a Nash equilibrium of the stage game.
In other words, if we look at any subgame in the final period of the game, that subgame is just the stage game itself; so in order for the strategies to be subgame perfect, they have to specify Nash equilibrium play in that game. In particular, neither player could make any promises to play in a way that wouldn’t be a Nash equilibrium of the stage game. (In this game, for example, player 1 can’t promise to play $\pone{B}$, and player 2 can’t promise to play $\ptwo{R}$, in the last period.)
But think about the following strategy for player 2:
- In the first period, play $\ptwo{R}$.
- In the second period, if $(\pone{B}, \ptwo{R})$ was played in the first period, play $\ptwo{L}$; otherwise, play $\ptwo{C}$.
What is player 1’s best response to this strategy? Well, in the second period, the best response is clear: since $\pone{T}$ is the best response to $\ptwo{L}$, and $\pone{M}$ is the best response to $\ptwo{C}$, player 1’s best response after the first game has been played must be
- In the second period, if $(\pone{B}, \ptwo{R})$ was played in the first period, play $\pone{T}$; otherwise, play $\pone{M}$.
Now the question comes: what should they do in the first period? Player 2 is playing $\ptwo{R}$; so it’s tempting for player 1 to choose $\pone{T}$ and get $\pone{9}$ rather than $\pone{7}$. But if they do that, then in the second period, the strategies specify that they’ll play $(\pone{M}, \ptwo{C})$, which gives player 1 a payoff of $\pone{2}$, so their total payoff over the two periods is $\pone{9 + 2 = 11}$. But if player 1 chooses $\pone{B}$ in the first period, then $(\pone{T}, \ptwo{L})$ will be played in the second game, so their payoff will be $\pone{7 + 5 = 12}$! Therefore their best response to player 2’s strategy is to play $\pone{B}$ in the first period!
Let’s see how this works in a game tree. It would be too much to have the entire tree (there would be 81 terminal nodes!) but here’s a version “as if” player 1 could choose between $\pone{T}$ and $\pone{B}$ in the first period, and $\pone{T}$ and $\pone{M}$ in the second period; and player 2 could choose between $\ptwo{L}$ and $\ptwo{R}$ in the first period, and $\ptwo{L}$ and $\ptwo{C}$ in the second period. You can see that in each of the four subgames (after $(\pone{T}, \ptwo{L})$, $(\pone{T}, \ptwo{R})$, $(\pone{B}, \ptwo{L})$, and $(\pone{B}, \ptwo{R})$), the two possible Nash equilibria are $(\pone{T}, \ptwo{L})$ and $(\pone{M}, \ptwo{C})$. The tree represents the SPNE we found above. Try playing around with it, and confirm that there is no single unilateral deviation that either player could play which would constitute a higher payoff for them!
What in God’s green earth is going on here?!
Let’s look at this intuitively rather than with all this game-theory jargon.
- In the stage game, there are two Nash equilibria: $(\pone{T}, \ptwo{L})$ and $(\pone{M}, \ptwo{C})$.
- In the second period, one of those two has to be played.
- Both players know that $(\pone{T}, \ptwo{L})$ is better for player 1, and $(\pone{M}, \ptwo{C})$ is better for player 2.
- They also know that $(\pone{B}, \ptwo{R})$ would be great to play in the first period, but that player 1 has an incentive to deviate to $\pone{T}$.
- So, they agree that if they’re able to play $(\pone{B}, \ptwo{R})$ in the first period, they’ll reward player 1 by playing the equilibrium that’s better for them in the second period.
By the way, it’s important to be sure that player 2 wants to go along with this plan! Note that player 2 could trigger the equilibrium that’s better for them in the second period by defecting to $\ptwo{L}$ in the first period; this would give them a payoff of $\ptwo{6 + 4 = 10}$. But in the equilibrium described above, they would be getting $\ptwo{9 + 2 = 11}$, so they don’t have an incentive to tank the deal.
Summary of the Two-Period Model
- In a finitely repeated game, a subgame-perfect Nash equilibrium must specify a Nash equilibrium in the final period of the game.
- If there are multiple Nash equilibria of the stage game, different equilibria can be played based on what happens early in the game.
- This allows players to credibly promise to play a “good” equilibrium (or credibly threaten to play a “bad” equilibrium) for the other players in early rounds of the game.
Infinitely (or Indefinitely) Repeated Games
Recall the prisoners’ dilemma from our first lecture on game theory. Think about the following simple version of this game, in which you can choose to cooperate or defect.
The idea here is that there is a cooperation payoff, which is what both players get if they cooperate. There’s also a betrayal payoff, which is what you get if you defect while the other person cooperates. And finally there’s the Nash payoff, which is what both players get if they both defect. The fundamental tension of the prisoners’ dilemma is that the cooperation payoff is worse than the betrayal payoff, but better than the Nash payoff. (And the Nash payoff is better than being betrayed.)
In this context, “sustaining cooperation” means finding a way for the players to cooperate, even in the face of an opportunity to gain a higher payoff when defecting. It’s clear that if this game is played only once, the only Nash equilibrium is for both players to defect. But what if you play more than once?
If you play the game a known, finite number of times, backward induction says that there’s only one solution: defection in every period. Why? Suppose the game was repeated twice. Well, in the second period, you know everyone is going to defect, because that subgame is just the same as the one-shot game. And if that’s known, there’s no credible threat or promise that can be made in the first period; so the only possible outcome in the first period is defection as well. Likewise, if the game is repeated $T$ times, even if $T$ is very large (like a billion!) we know that defection is coming at the end; so defection is the only possibility in stage $T-1$; so it’s got to be the only possibility in $T-2$; and so on, all the way back to the first stage.
But what if the game goes on indefinitely – that is, with no known end? Then the possibility of the game continuing can potentially open up more equilibrium outcomes.
Evaluating Payoffs in Games Without Endings
In order to analyze this type of game, we need some well-defined notion of a payoff. We can’t say the payoff is what you get at the end of the game, because it doesn’t have a concrete ending point! But we also can’t add up an infinite number of payoffs…we’d get infinity.
Many textbooks (and some homework exercises) refer to this type of game as an infinitely repeated game: that is, a game without end. But that doesn’t make any logical sense; for one thing, people don’t live forever. So the way they get around this is to say that there’s a discount factor $\delta$ which measures how much you care about payoffs one period from now, as a fraction of how much you care about present payoffs. (This is exactly the same as the $\beta$ discount factor we talked about when we were dealing with intertemporal choice.) With this framework, as long as $\delta < 1$, even though the game is “infinite,” you don’t really care about payoffs that occur far into the future; so the payoff from an infinite stream is well-defined: in particular, the “present value” $V$ of receiving a payoff of $x_0$ now, $x_1$ one period in the future, $x_2$ two periods in the future, and so on, is \(V(x_0,x_1,x_2,x_3,...) = x_0 + \delta x_1 + \delta^2 x_2 + \delta^3 x_3 + \cdots\)
There’s another equivalent way of looking at the same mathematical objects, though, and I think it makes a lot more intuitive sense. Even if a relationship doesn’t last forever, you don’t know exactly when it’s going to end. If we let $\delta$ be the probability that the game continues to the next stage, then $V$ is your expected payoff, and we get the same exact formula! (I’ll go over the derivation in class in a bit more detail.)
There’s an interesting special case of this: the value of receiving some amount $x$ now for every period afterward, as long as the game is going on, is \(V(x) = x + \delta x + \delta^2 x + \delta^3 x + \cdots\) Note that if we factor out the $\delta$ from the remaining terms, we get \(V(x) = x + \delta \left[x + \delta x + \delta ^2x + \cdots \right]\) But the bracketed term is just $V(x)$ again! Substituting this in and solving for $V(x)$ gives us \(\begin{aligned} V(x) &= x + \delta V(x)\\ (1-\delta)V(x) &= x\\ V(x) &= {x \over 1 - \delta} \end{aligned}\) Let’s do a sanity check. We said that \(V(x) = x + \delta V(x)\) If we plug the expression for $V(x)$ in here, we have \(\begin{aligned} V(x) &= x + \delta \left(x \over 1 - \delta\right)\\ &= \underbrace{\left({1 - \delta \over 1 - \delta}\right)}_1 x + \left({\delta \over 1- \delta}\right)x\\ &= \left({1 - \delta + \delta \over 1 - \delta}\right)x\\ &= {x \over 1 - \delta} \end{aligned}\) which confirms that this is, indeed, the correct formula!
Now that we’ve established how to evaluate payoffs, let’s talk strategies.
Strategies in Repeated Games
A repeated game is a type of dynamic game. Just as a strategy in a dynamic game had to specify what to do at any node, a strategy in a repeated game has to specify what to do at every possible history of a game.
Before you read on, I’d like you to go play an online game called “The Evolution of Trust” by Nicky Case. (There will be a quiz question about it!) The whole game takes about half an hour to play, but just doing the first 10 minutes or so is fine. Then come back here and continue reading. I’ll wait.
So, in the game, you meet a cast of characters. Each of those characters represents a potential strategy in the game. Nicky presents them as follows:
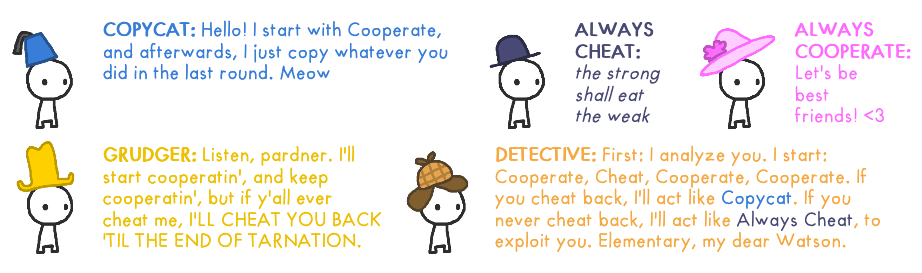
Importantly, each of these strategies maps any history of the game onto an action. Some, like “always cheat” and “always cooperate,” map every history onto the same action. (That’s ok, $f(x)=3$ is still a function, even though it returns 3 for every possible value of $x$!) Others, like Copycat, only use the last action played by the opposite player as the determinant of what to do. Still others, like Detective, are more complicated.
These aren’t the only possible strategies – indeed, there are an infinite number of strategies that are possible – but it’s useful to focus on a few of them, because they provide a finite number of testable scenarios. And in particular, we’re going to look at the strategy employed by Grudger, which economists call a “grim trigger” strategy. Let’s write it out a little more formally:
Definition (Grim Trigger Strategy): In an indefinitely repeated prisoners' dilemma style game, in which players choose between a cooperative action and a greedy one, a Grim Trigger strategy specifies that the agent should:
- start by playing the cooperative action;
- play the cooperative action in any history of the game in which no player has ever chosen to defect to the greedy option; and
- play the greedy action after every other history.
Let’s think about when such a strategy might be sustainable in equilibrium. Fundamentally, the strategy divides all possible histories of the game into two classes of subgame:
- Subgames after histories in which no one has ever deviated (including the first period). If you’re in this situation, you know the other player will cooperate. So, if you cooperate, you’ll get the cooperation payoff; and in the next period you will be back in this same situation. If you defect, you will get the betrayal payoff for one period; then, in the next period, you’ll be in the second type of history.
- Subgames after histories in which at least one player has defected to the greedy option. In this case you know that they’re going to play the greedy option, and will in every period after this no matter what you do.
Suppose you are playing against someone playing this strategy, and the payoffs are as given in the following matrix. What is your best response?
If anyone has ever defected, you should clearly defect; your opponent is going to defect, and given that, you should as well. You’re stuck in the prisoners’ dilemma and there’s no getting out.
But if no one has ever defected, you face a choice. If you cooperate, you’ll get the cooperation payoff now, and next period you’ll be in the same situation; and since if this is optimal now it will always be optimal, you’ll get the cooperation payoff forever. But if you defect, you get the betrayal payoff once, and then the Nash payoff forever. When this is worth it depends on the relative payoffs and the value of $\delta$:
Try changing $\delta$ to confirm the cutoff value; then try playing around with the payoffs and the value of $\delta$ to see how the calculations change!
Application: Collusion in the Cournot Model
To wrap up this unit, let’s return one last time to the Cournot model. We’ll keep to the same parameters of the model we’ve been dealing with: market demand is given by $P(Q) = 14 - Q$, and each firm can produce at a cost of 2 per unit:
We found in lecture 9 that the best response functions for each firm were \(BR_i(q_{-i}) = \begin{cases}6 - \tfrac{1}{2}q_{-i} & \text{ if }q_{-i} \le 12\\0 & \text{ if }q_{-i} \ge 12\end{cases}\) and that the Nash equilibrium of the game was \(\pone{q_1} = \ptwo{q_2} = 4\) under which each firm got a payoff of 16.
What’s the best they could do, though, if they colluded? That is, if each of them agreed to produce some amount $q_C$, what’s the best they could do?
Well, in this case, each firm would earn a profit of \(\pi_i(q_C) = (14-2q_C)q_C - 2q_C = 12q_C - 2q_C^2\) Taking the derivative of this and setting it equal to zero gives us \(\pi_i^\prime(q_C) = 12 - 4q_C = 0 \Rightarrow q_C^\star = 3\) Indeed, in homework 4, you found that in this case they each made a profit of 18, which is higher than the Nash equilibrium profit of 16.
But, if the other firm is producing 3, your best response would be to produce $6 - {1 \over 2} \times 3 = 4.5$, which (as you can see if you play with the graph above) would give you a payoff of 20.25.
So essentially, we have a situation like the prisoner’s dilemma above, in which we have:
- Cooperative (collusive) payoff: 18
- Betrayal payoff: 20.25
- Nash (Cournot) equilibrium payoff: 16
By the same logic as above, the “grim trigger” strategy will be sustainable as long as $\delta$ is high enough so that earning 18 forever is better than getting 20.25 for one period, and 16 forever after: \(\begin{aligned} {18 \over 1-\delta} & \ge 20.25 + \delta \left({16 \over 1-\delta}\right)\\ 18 & \ge 20.25(1-\delta) + 16\delta\\ 4.25\delta & \ge 2.25\\ \delta & \ge {2.25 \over 4.25} = {9 \over 17} \end{aligned}\) We’ll talk at length in class about some real-world applications of this model, but that’s enough reading for now! See you in class.
Reading Quiz
That's it for today! Click here to take the quiz on this reading.